Bimsara Pathiraja
I am a fourth-year PhD student in Computer Science at Arizona State University, advised by Chitta Baral and Yezhou Yang. I work on generative models for images, video and speech, mostly on steering them at inference time without retraining.
I have spent two summers as an Applied Scientist Intern at Amazon, working on expressive speech generation and on object detection and tracking. Before ASU I was a research assistant at MBZUAI with Muhammad Haris Khan, and before that I studied Electronic and Telecommunication Engineering at the University of Moratuwa, Sri Lanka.
News
- [Sep 2026] Discriminant Flow Steering, on training-free capability transfer between flow-matching image models, is under review.
- [Aug 2026] Finished my second Applied Scientist internship at Amazon, in Seattle.
- [Jun 2025] RefEdit accepted at ICCV 2025.
- [May 2025] Started an Applied Scientist internship at Amazon.
- [Mar 2025] Our U.S. patent application on calibrating object detectors was published. Link
- [Jan 2025] Paper on step-by-step legal reasoning in LLMs accepted at NAACL 2025 Findings.
- [Aug 2023] Joined Arizona State University as a PhD student and received the Fulton Fellow Award.
- [Feb 2023] Paper on calibrating object detectors accepted at CVPR 2023.
Publications
* denotes joint first authors
-
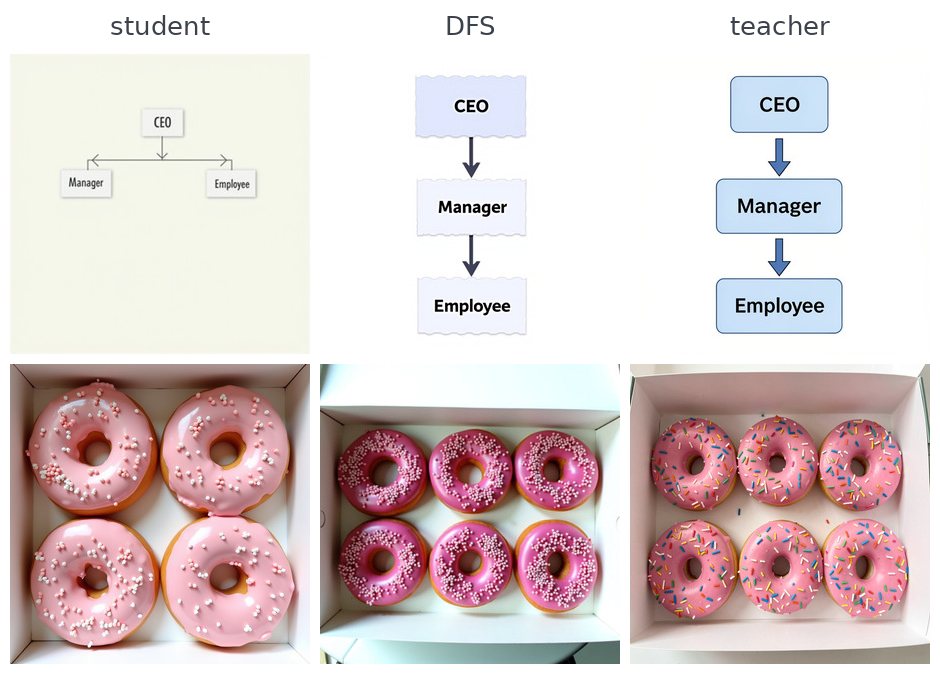 Discriminant Flow Steering: Training-Free Capability Transfer in Flow-Matching Models
Bimsara Pathiraja, Agneet Chatterjee, Chitta Baral, Yezhou Yang
Under reviewMoves a capability from a black-box teacher into an open flow-matching model using about twenty of the teacher’s images, with no training and no extra cost at inference.
-
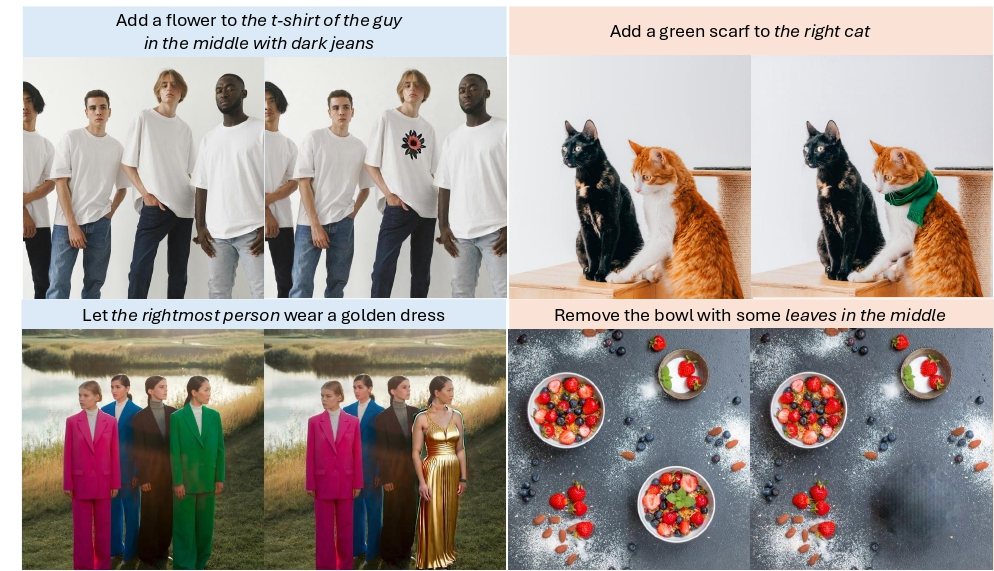 RefEdit: A Benchmark and Method for Improving Instruction-based Image Editing Model on Referring Expressions
Bimsara Pathiraja*, Maitreya Patel*, Shivam Singh, Yezhou Yang, Chitta Baral
ICCV 2025
Paper / Project / Code / Data -
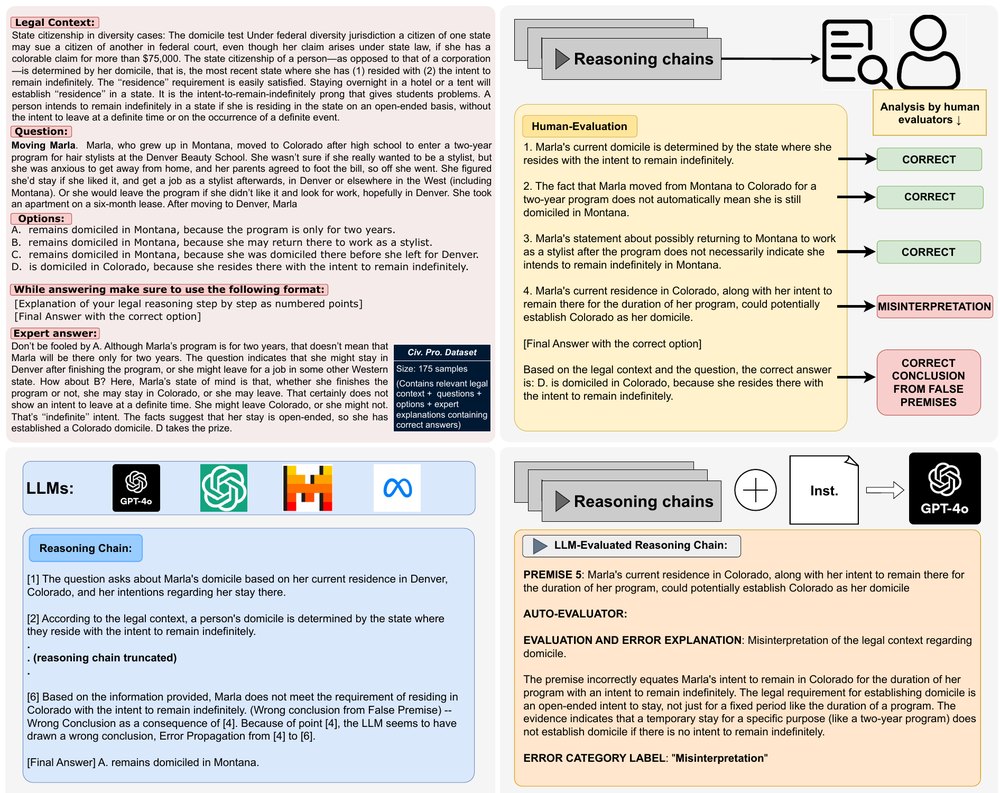 Investigating the Shortcomings of LLMs in Step-by-Step Legal Reasoning
Venkatesh Mishra*, Bimsara Pathiraja*, Mihir Parmar, Sat Chidananda, Jayanth Srinivasa, Gaowen Liu, Ali Payani, Chitta Baral
NAACL 2025 Findings
Paper / Code -
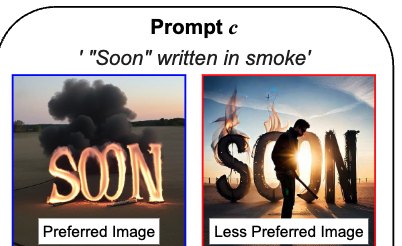 Dual Caption Preference Optimization for Diffusion Models
Amir Saeidi, Yiran Luo, Agneet Chatterjee, Shamanthak Hegde, Bimsara Pathiraja, Yezhou Yang, Chitta Baral
TMLR 2025
Paper -
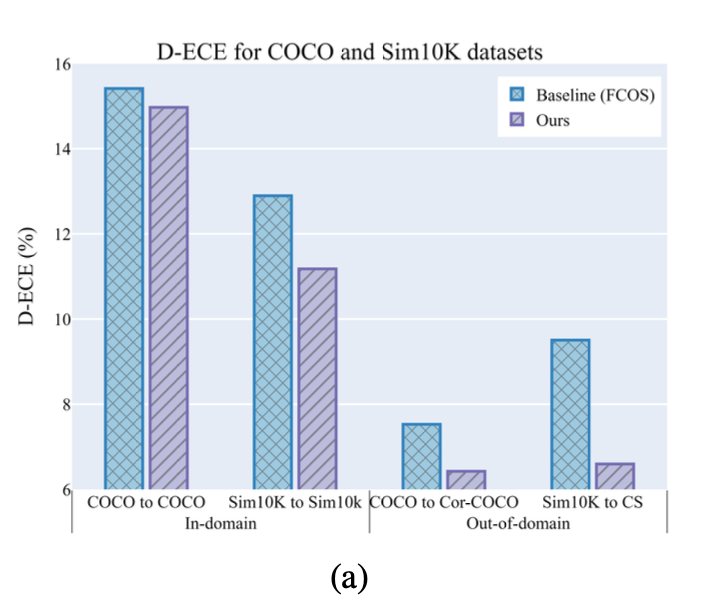 Multiclass Confidence and Localization Calibration for Object Detection
Bimsara Pathiraja, Malitha Gunawardhana, Muhammad Haris Khan
CVPR 2023
Paper / Code / U.S. patent application -
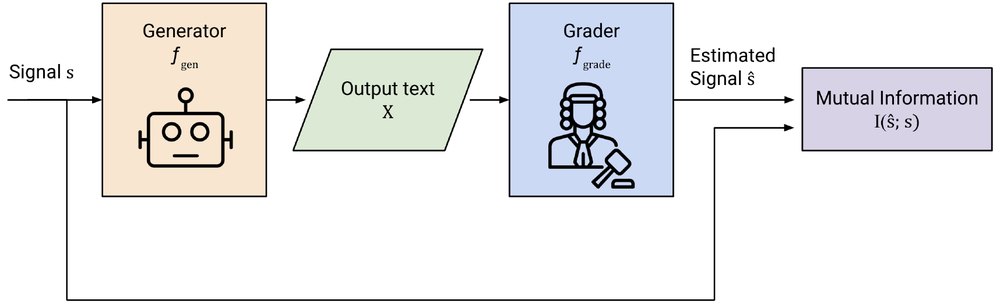 ExpressivityBench: Can LLMs Communicate Implicitly?
Joshua Tint, Som Sagar, Aditya Taparia, Kelly Raines, Bimsara Pathiraja, Caleb Liu, Ransalu Senanayake
Findings of EACL 2026 (earlier version at the NeurIPS 2024 Workshop on Behavioral ML)
Paper -
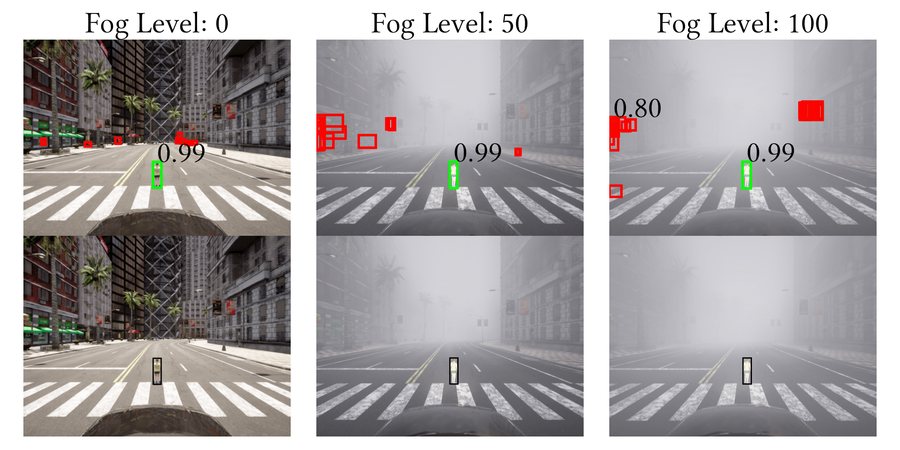 Fairness in Autonomous Driving: Towards Understanding Confounding Factors in Object Detection under Challenging Weather
Bimsara Pathiraja, Caleb Liu, Ransalu Senanayake
CVPR 2024 Workshop on Data-Driven Autonomous Driving Simulation
Paper / Project / Code -
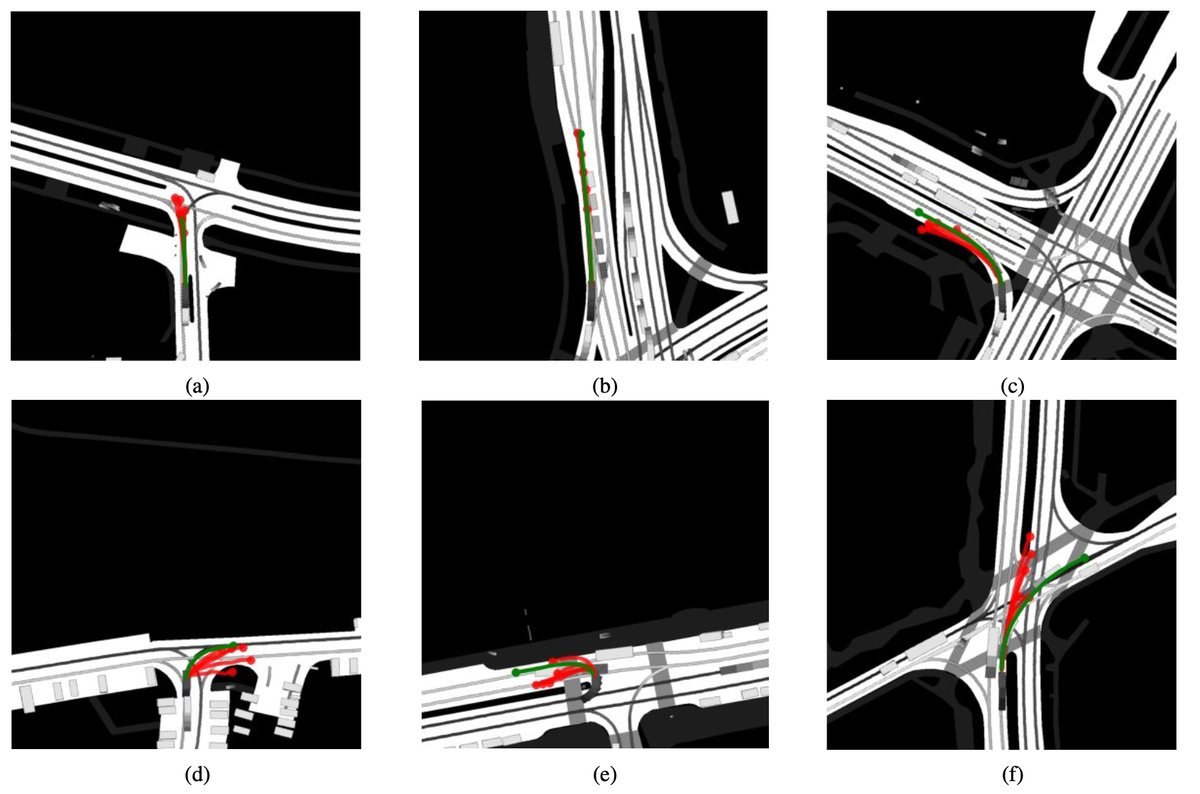 Class-Aware Attention for Multimodal Trajectory Prediction
Bimsara Pathiraja, Shehan Munasinghe, Malshan Ranawella, Maleesha De Silva, Ranga Rodrigo, Peshala Jayasekara
arXiv 2022
Paper
Outside research
I dance Latin ballroom, cook, work out, and read a lot of non-fiction.
Books I recommend
- Sapiens Yuval Noah Harari
- 21 Lessons for the 21st Century Yuval Noah Harari
- Man’s Search for Meaning Viktor E. Frankl
- A Briefer History of Time Stephen Hawking
- Zero to One Peter Thiel
- Permanent Record Edward Snowden
- Becoming Michelle Obama
- 12 Rules for Life Jordan Peterson
- The Art of War Sun Tzu
- The Monk Who Sold His Ferrari Robin Sharma
- The Subtle Art of Not Giving a F*ck Mark Manson
- Hyperbole and a Half Allie Brosh
- The Hitchhiker’s Guide to the Galaxy Douglas Adams
- Crime and Punishment Fyodor Dostoevsky
- The Archer Paulo Coelho